
A new kind of AI just showed up, and it refuses to talk. The Jev AI model outputs nothing but probabilities, and developers are already using it to cut automation costs by 10 to 20 times. That sounds bizarre until you see why it works.
What the Jev AI model actually is
Most AI you’ve touched is a chatbot at heart. You type words, it types words back. Jev skips that entirely. It’s a transformer-based model that never writes text. Instead, it hands back a probability, something like “87% chance this email is a refund request.”
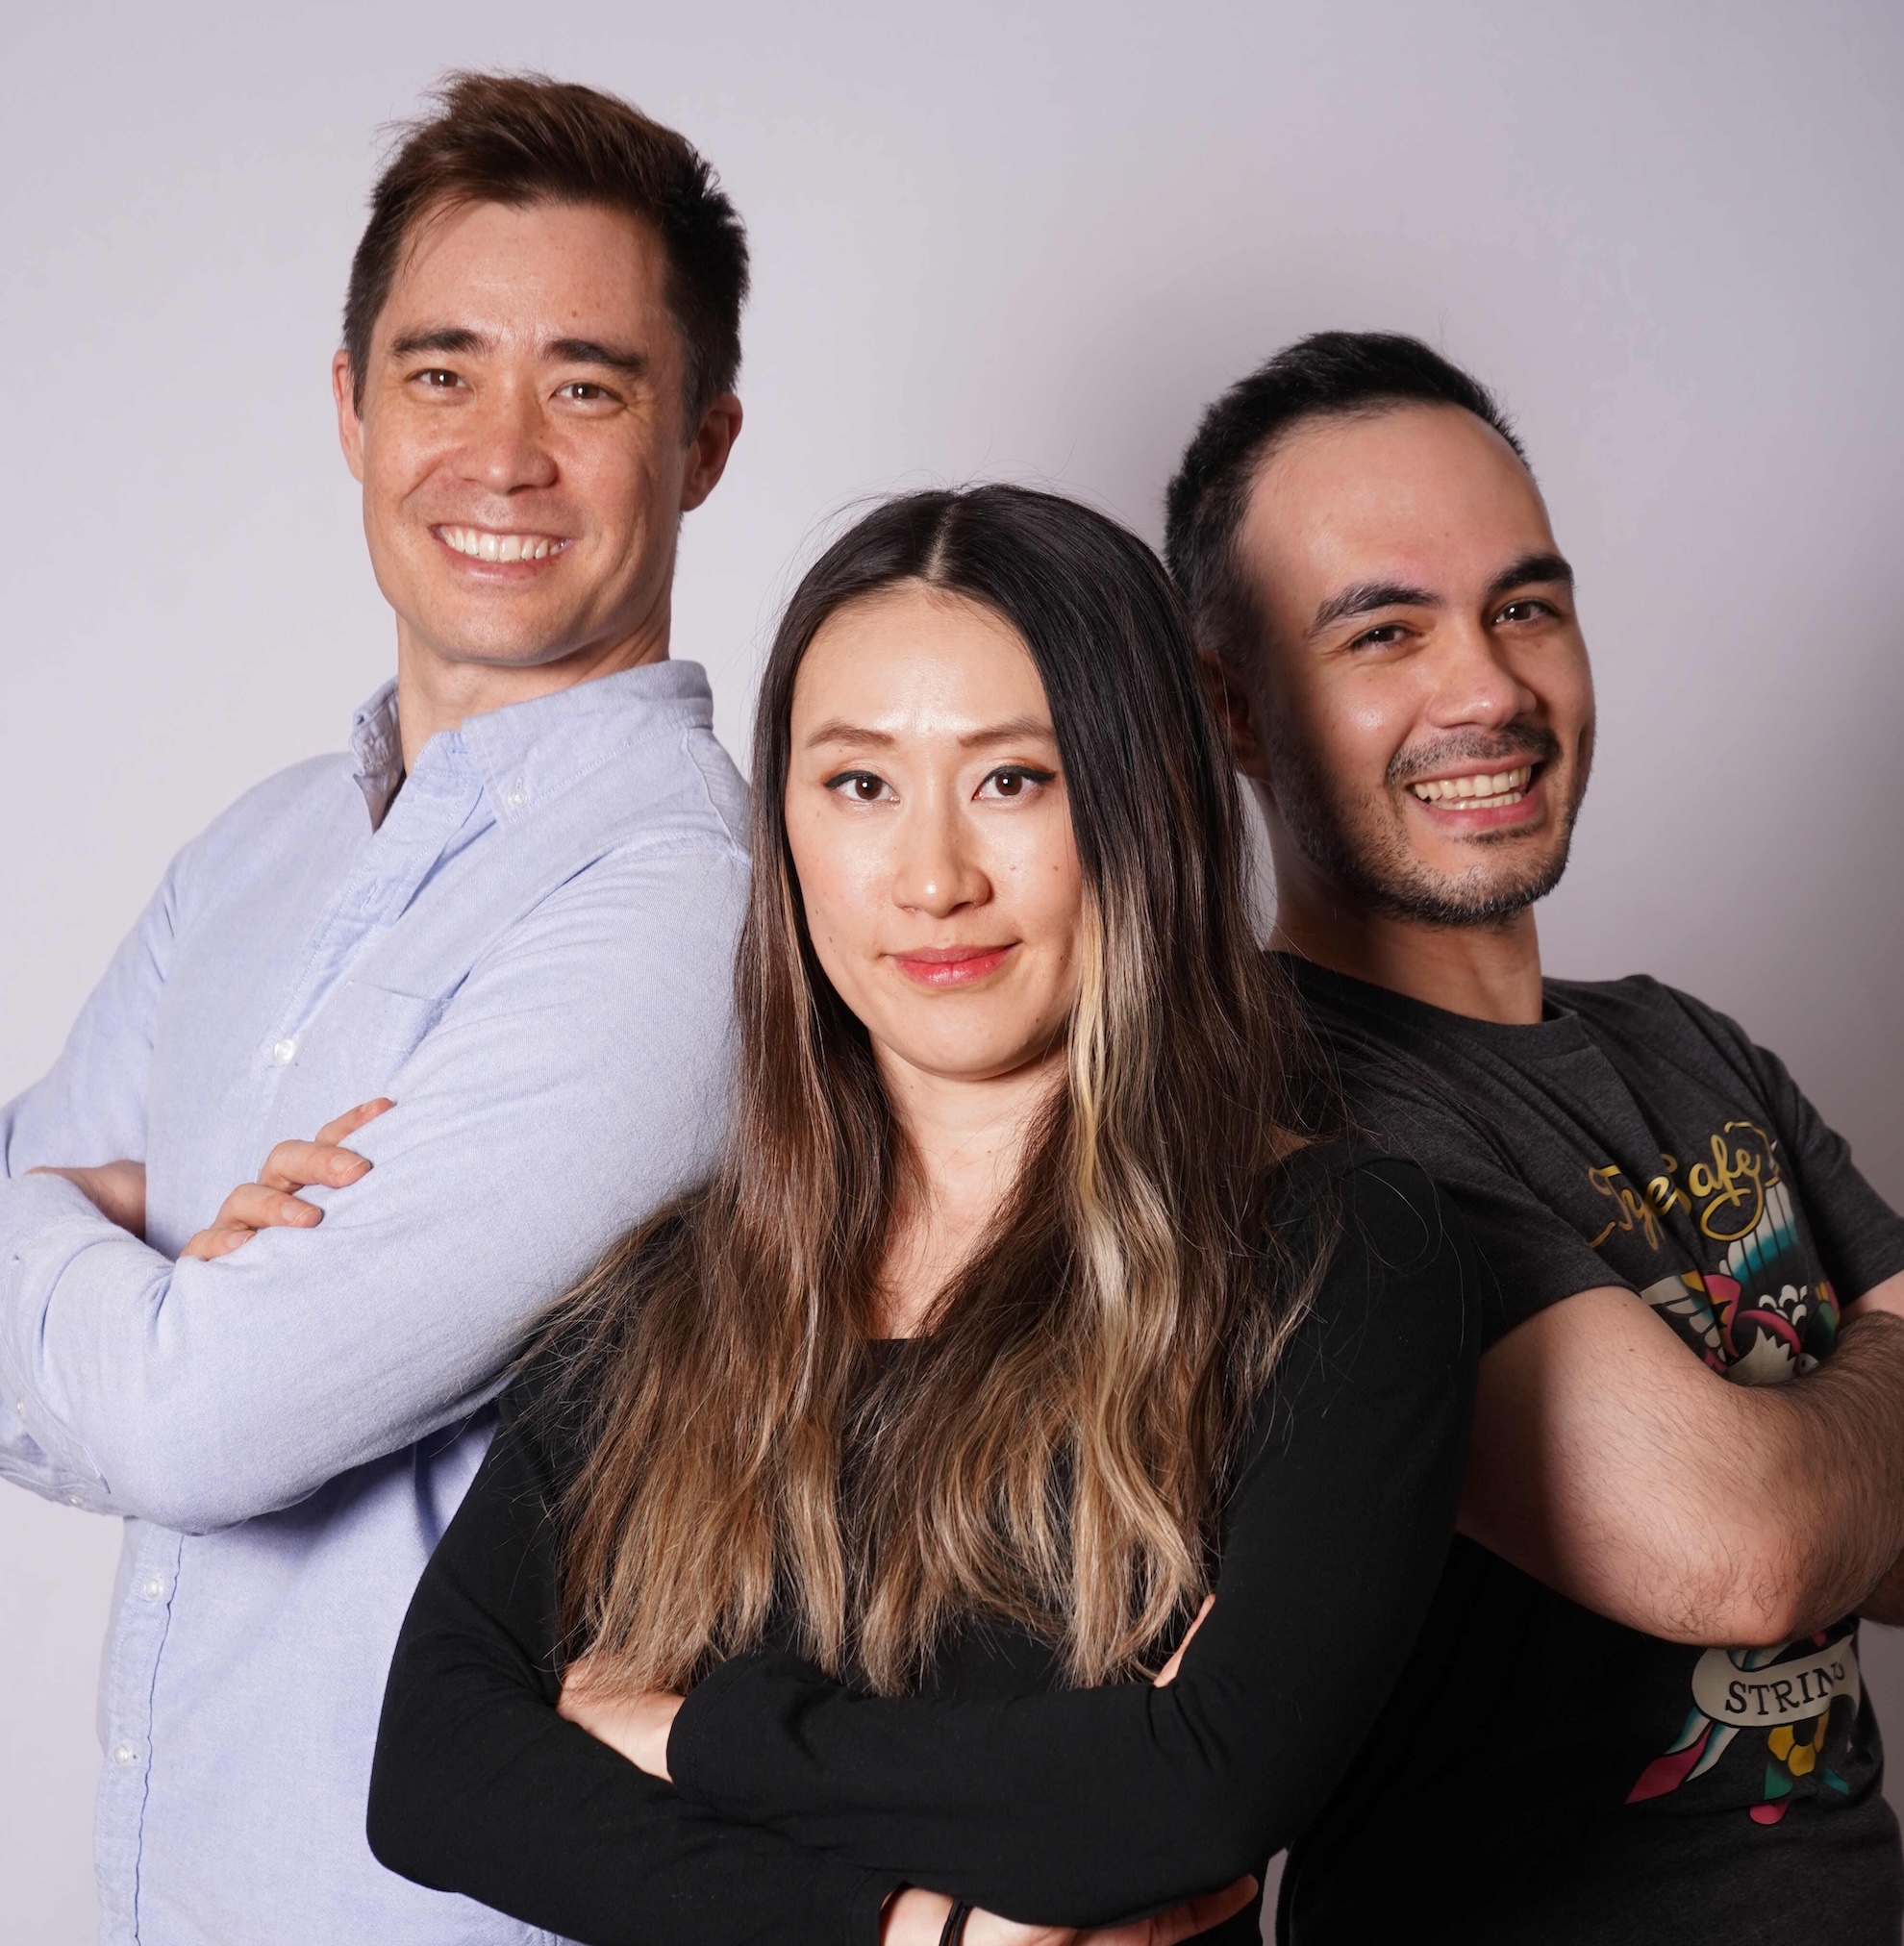
TypeSafe, the startup behind it, calls these “calibrated decisions.” You define the possible outputs in advance, and the model picks between them with a confidence score attached. That’s it. No paragraphs, no essays, no hallucinated facts.
Here’s the kicker: because the outputs are predefined, it can’t make things up. Hallucination becomes impossible by design, not by careful prompting.
Built by an OpenAI veteran
The founder story matters here. Diogo Almeida helped build ChatGPT and worked on RLHF, the training technique behind most modern AI assistants. Two years ago he left OpenAI to start TypeSafe because he thought something was broken.
His argument: developers keep using giant chat models for tiny decisions. Should this command run? Is this review toxic? Which tool should the agent call next? Those are yes-or-no questions, and paying GPT-class prices to answer them is wasteful.
Demand for the launch briefly knocked TypeSafe’s API offline. For a no-text model, that’s a lot of noise.
Why “System One”
Almeida borrows from psychology. Your brain has fast, automatic judgment (System 1) and slow, deliberate reasoning (System 2). Chat models are built for System 2 work. Jev is built for System 1: quick classification with a number attached.
The name itself is an economics joke. William Stanley Jevons described how making a resource cheaper makes people use more of it, not less. Cheap decisions mean more decisions.
Why skipping text makes it so cheap
Token pricing punishes you twice. You pay for the prompt going in and the words coming out. For a one-word answer, the output cost is tiny, but the model still thinks in full sentences internally, and at scale those costs pile up.
Jev flips the billing model. Output tokens are free, and input is metered by the billion rather than the million. So instead of pennies per thousand classifications, you’re fractions of a cent per million.
There’s a second benefit people notice less at first. Chat models are slow because generating words takes time, one token after another. The Jev AI model returns a number instead, so latency drops hard. Speed matters when a decision sits inside a loop that runs thousands of times.
The numbers from real-world tests
Two public test results came out with the launch, and both point the same direction.
| Test | Before (LLM) | With Jev |
|---|---|---|
| Command-safety checks at Vercel | ChatGPT Luna 5.6 | 5 to 18 times faster, with greater accuracy |
| Business email classification at Bryo AI | Gemini | Gemini slightly more accurate, but 10 to 20 times more expensive |
| Output tokens | Billed per token | Free |
| Hallucination risk | Possible | Impossible by design |
| Confidence score | Often vague | Real probability returned |
The email test is the honest one. Gemini actually won on raw accuracy, slightly. However, the Bryo AI CTO pointed out that Jev was the only model handing back a real probability, which made automation safer: you can set rules like “act above 90% confidence, ask a human below it.”
That’s the pattern worth stealing. You don’t need the smartest model for every step. You need the right model with honest uncertainty.
Where Jev fits in your stack
You probably won’t chat with the Jev AI model directly. You’ll benefit from it without noticing. Likely landing spots:
- Inbox and ticket routing: sort thousands of messages into categories every hour.
- Moderation: flag spam, scams, or hostile comments before they reach a human.
- Agent guardrails: let an AI assistant act only when a check passes, like a bouncer at the door.
- Data cleanup: classify messy spreadsheet rows into clean labels.
If you’ve built any automation with AI, you already have a dozen spots where a chat model answers a multiple-choice question. Those spots are what it eats.
Under the hood, the architecture stays secret. Outside observers suspect it’s built on top of an open-weight LLM and then trained hard on synthetic data with a technique TypeSafe calls RLCD (reinforcement learning from calibrated decisions). Whatever the recipe, the company owns its data pipeline, and Almeida says that’s the real moat.
What Jev can’t do
Let’s keep this honest. It won’t write your emails, summarize documents, or reason through a tricky problem. Any task that needs generated language needs a language model.
It also won’t beat a big LLM on raw accuracy in every case. The Gemini test showed that. The pitch is cost and speed at acceptable accuracy, with honest confidence scores. For high-stakes judgment calls, you still want the bigger brain.
And there’s a lock-in question. The model is closed about how it works inside, so you’re trusting TypeSafe’s numbers. Early days. Watch how the benchmarks hold up as independent testers dig in.
What we still don’t know
Honest gaps, so you don’t get burned by hype:
- Exact pricing. The launch coverage describes the billing shape (free outputs, input metered by the billion) but publishes no price list. Wait for real invoices before rewriting your budget.
- The architecture. TypeSafe is tight-lipped. Observers suspect an open-weight base model underneath. If true, copies could appear fast, and prices could drop faster.
- Long-term reliability. Two glowing launch tests are a start, not a track record. Calibration claims deserve independent benchmarks, and those take a few months.
- Where you can even buy it. Access is via TypeSafe’s API today. Self-hosted or marketplace availability isn’t announced.
None of these kill the story. They just mean: interesting now, safer to bet on in a quarter.
Should you care about the Jev AI model?
If you run automations, yes, this one’s worth 20 minutes of your time. The direction matters more than the product: AI is splitting into “thinkers” and “reacters,” and the reacters are dirt cheap. The Jev AI model won’t stay alone for long, either. Expect copycats within months, which usually means prices fall further.
If you’re a beginner with no automations yet, file this under “why my tools keep getting cheaper.” Every time a decision inside a workflow gets 10 times cheaper, apps you use get faster and freemium plans get more generous.
My take? The most underrated detail is the confidence score. Most chat models give you an answer with fake certainty. A model that says “78% sure” lets you build automations that know when to ask for help. That’s how you avoid embarrassing AI mistakes at scale.
Your next step
Check your current workflows for chat-model calls that answer simple questions. Sort, flag, route, approve: those are Jev-shaped problems. Read the TechCrunch launch coverage, and if you’re paying per-call for classification today, wait for the copycats and compare prices in a month.
Meanwhile, if you want to cut AI costs elsewhere, see how model routing cuts spending by up to 90%, or try a free coding model like Qwen 3.8 before you pay for another subscription. Cheap decisions add up fast.