
AI used to help you write code. Now it chooses what code to write, runs the experiments, and tells you what worked. The pipeline didn’t just get faster — it got automated.
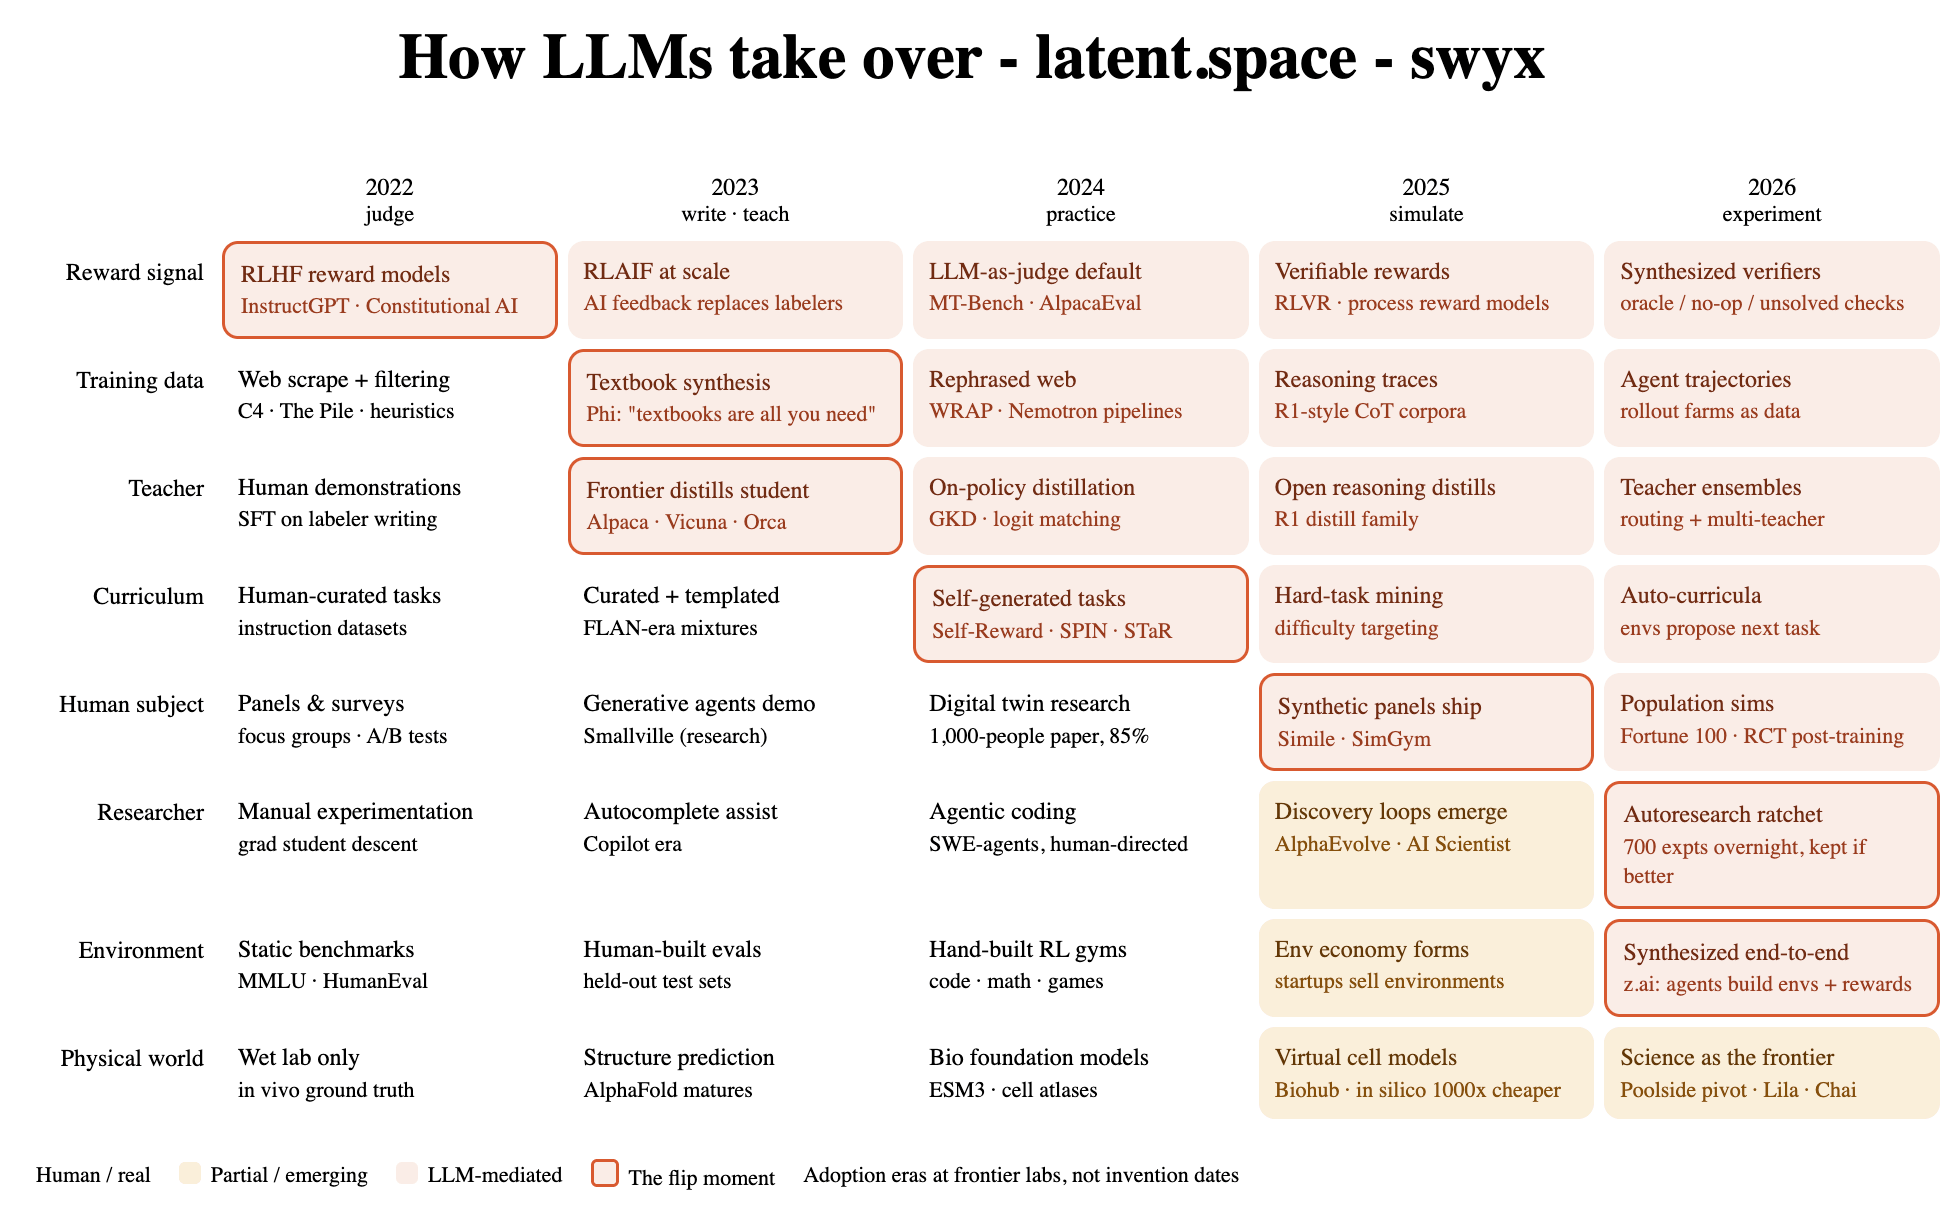
Every year since 2022, one more component of the machine intelligence pipeline flipped from human-made to model-made. Not gradually. Each flip has a patient zero — a paper or product where the synthetic version first became load-bearing at a frontier lab. From there, the future is simply here but not yet productionized.
The pattern is consistent: 10% worse, 100x cheaper, 10,000x faster. Each stage follows this curve. What we used to call “synthetic data” and “synthetic rubrics” and “AI researcher” is just increasingly ambitious human simulation.
Here’s the map of all 8 stages — where we are, what flipped, and what it means for you.
The Pattern: 10% Worse, 100x Cheaper, 10,000x Faster
Before diving in, understand the tradeoff. The synthetic version is slightly lower quality — about 10% worse on benchmarks. But it costs 100x less and runs 10,000x faster.
For the lab, that’s a no-brainer. For you? It means the tools automating each stage are already good enough to replace the human step for most practical purposes. The question isn’t “is it perfect?” — it’s “does it unblock me?”
The 8 Stages at a Glance
| Stage | Component | Year Flipped | Patient Zero | What It Means |
|——-|———–|————–|————–|—————|
| 1 | Reward Signal (Judge) | 2022 | InstructGPT / Constitutional AI | Models judge models |
| 2 | Training Data | 2023 | Phi / Apple WRAP / Nemotron | Models write textbooks |
| 3 | Teacher (Distillation) | 2023 | Alpaca / Vicuna / DeepSeek-R1 | Models teach models |
| 4 | Curriculum | 2024 | Self-Rewarding LMs / SPIN | Models choose what to learn |
| 5 | Researcher | 2026 | AlphaEvolve / AI Scientist / autoresearch | Models run experiments |
| 6 | Environment | 2026 | Z.ai / Ornith-1.5 | Models build RL worlds |
| 7 | Human Subject | 2025+ | Generative Agents / Simile | Models simulate humans |
| 8 | Physical World | 2026+ | Poolside / CZ Biohub | Wet labs remain (for now) |
—
Stages 1-3: Done — Judge, Data, Teacher
Stage 1: The Judge Flipped (2022)
Before: Humans rate model outputs. Slow, expensive, inconsistent.
After: InstructGPT trained a reward model on human preferences once, then let the policy optimize against the model, not the humans. Constitutional AI went further — the AI critiques itself against principles. By 2023, LLM-as-judge (MT-Bench, AlpacaEval) became the default evaluation methodology.
Now: The entire approval apparatus — reward, critique, evaluation — runs on models judging models.
For you: When you use an LLM to evaluate another LLM’s output (or your own writing), you’re using Stage 1 automation.
Stage 2: The Data Flipped (2023)
Before: Human-written text scraped from the web.
After: Microsoft’s Phi series proved “Textbooks Are All You Need” — small models trained on LLM-synthesized textbook data punched far above their weight. Apple’s WRAP generalized: rephrase the entire web with an LLM, get 3x pretraining efficiency. NVIDIA’s Nemotron-4 340B shipped a permissive synthetic data pipeline. By 2025, reasoning traces (chains of thought from strong models) became standard pretraining ingredients.
Now: The pretraining corpus is substantially model-written.
For you: The “data moat” is gone. Quality synthetic data is commoditized. Don’t build a business on proprietary datasets.
Stage 3: The Teacher Flipped (2023)
Before: Human demonstrations for fine-tuning.
After: Stanford’s Alpaca showed a $600 fine-tune on GPT-generated instructions could clone frontier behavior. Vicuna used shared conversations. Orca used rich teacher explanations. DeepSeek-R1 shipped distilled models alongside the flagship — making “the teacher is a model” the default for every small model release.
Now: Distillation is industrialized. The knowledge transfer is model-to-model.
For you: You can get 90% of a flagship model’s capability in a fraction of the size/cost. Stop chasing the biggest model — chase the best distilled model for your hardware.
—
Stages 4-6: Flipping Now — Curriculum, Researcher, Environment
Stage 4: The Curriculum Flipped (2024)
Before: Humans choose what to train on next. Artisanal, taste-driven.
After: Self-Instruct (models writing own instruction sets) and STaR (models bootstrapping own reasoning traces) existed in 2022. But the flip came when Meta’s Self-Rewarding Language Models and SPIN showed a model could generate its own tasks, judge its own outputs, and improve past the ceiling of human preference data.
Now: Curriculum design — historically the most artisanal part of ML — is something models do to themselves.
For you: Fine-tuning pipelines that auto-generate training curricula are hitting the market. The “prompt engineering” skill is being automated from the top down.
Stage 5: The Researcher Flipped (2026)
Before: Humans choose experiments. Copilot, SWE-agents — assistance era.
After: The discovery era. DeepMind’s AlphaEvolve evolved genuinely new algorithms (2025). Sakana’s AI Scientist sketched the full paper-writing pipeline (Nature, 2026). The big moment: Andrej Karpathy’s autoresearch (March 2026) — a minimal ratchet loop where a coding agent modifies a real LLM training setup, runs a 5-minute experiment, keeps the change only if validation loss improves, and repeats overnight.
Result: 700 experiments → 20 kept improvements. GPT-2 training time cut from 2.02 to 1.80 hours. Real, transferable code changes found while he slept.
Now: Agents choose AND run experiments autonomously. The human chooses the problem; the agent solves it.
For you: If you’re optimizing prompts, hyperparameters, or architectures — that’s being automated. The lever moves to: problem definition and result judgment.
Stage 6: The Environment Flipped (2026)
Before: Humans build RL environments. Slow, brittle, limited.
After: RL’s bottleneck moved from model to environment. You need thousands of executable, verifiable task worlds. Z.ai built pipelines that synthesize environments end-to-end: research agents mine real work patterns → long-horizon environments with hidden state → judge agents confirm solvable → verifiers synthesized without seeing the reference solution → stress-tested until binary reward is reliable.
Quote from GLM-5.3 release: “The entire environment, judging, and verification stack is synthetic all the way down.”
Ornith-1.5 shipped same week: model proposes own tasks, generates own RL rollouts. The gym, the referee, and the scoreboard are all models now.
Now: Infinite, diverse, verifiable training environments generated on demand.
For you: RL — previously a PhD specialty — is becoming accessible via synthetic environments. Tools that let you “simulate the task” before deploying are the next wave.
—
Stages 7-8: In Progress — Human Subject, Physical World
Stage 7: The Human Subject (2025+)
Before: Focus groups, user studies, A/B tests with real humans.
After: Generative Agents (Smallville, 2023) simulated a town of AI agents. The 1,000-person simulation (2024) built digital twins from 2-hour interviews — reproduced source humans’ survey and behavioral responses 85% as accurately as humans reproduced themselves two weeks later.
Simile post-trains on interviews, transaction data, and registered RCTs to recover human bias, inconsistency, and causal texture. SimGym at Shopify simulates shopper trajectories. Tencent’s billion-persona approach at the crude end.
Now: Focus groups, user studies, and A/B test panels are becoming inference workloads.
For you: Product validation that used to take weeks and thousands of dollars can run in minutes for cents. But — the simulations reflect average humans. Edge cases, cultural nuances, and genuine novelty still need real people.
Stage 8: The Physical World (2026+, In Progress)
Before: Wet labs, clinical trials, field tests, manufacturing runs.
After: This one hasn’t flipped. Poolside drew the line: “intelligence-bound” problems (solvable by scaling cognition) vs “experiment-bound” problems (where “no amount of intelligence substitutes for real-world experimental feedback — 100,000 brilliant minds won’t cure cancer without a wet lab”).
CZ Biohub is imaging human cells at scale. Automated labs are emerging. But the physical loop — hypothesis → experiment → measurement → update — remains the hard ceiling.
Now: AI designs the experiment, predicts the outcome, optimizes the protocol. Humans (or robots) still run the physical trial.
For you: If your work involves physical constraints (biology, materials, hardware, regulation), AI is a powerful co-pilot but not the pilot. The moat is experimental throughput, not intelligence.
—
What This Means for Your Tool Choices Today
Don’t learn skills that Stage 3 just automated. Writing training data, creating demonstrations, designing fine-tuning curricula — tools do this better/faster/cheaper.
Do invest in Stage 4-6 tools: Auto-curriculum fine-tuning, experiment orchestration (autoresearch-style), synthetic environment generation. These are the current frontier.
Do build for Stage 7-8 human territory: Problem definition, experimental design for physical systems, ethical oversight, resource allocation, novel hypothesis generation. The further up the stack, the more human leverage remains.
Tool selection heuristic: Pick tools that automate the stage you’re currently doing manually, not the stage that’s already done. If you’re still hand-labeling data, get a Stage 2 tool. If you’re hand-tuning hyperparameters, get a Stage 5 tool.
—
What This Means for Your Career / Learning Path
The “AI researcher” role is splitting:
- Harness engineers — build the scaffolding (Stages 4-6 tooling)
- Experiment designers — define what to measure in physical systems (Stage 8)
- Product definers — specify the problem worth solving (pre-Stage 1)
The pure “model builder” — architecture, data, training loop — is being compressed into automated pipelines. The value shifts to: what problem, for whom, measured how, constrained by what reality?
—
Your Takeaway: Aim for the Human Territory
The pipeline is automating from the bottom up. Stage 1-3: done. Stage 4-6: flipping now. Stage 7-8: human territory (for now).
Your move: Don’t compete with the automation. Build on top of it.
- Use synthetic data (Stage 2) instead of scraping
- Use distilled models (Stage 3) instead of training from scratch
- Use auto-curriculum (Stage 4) instead of hand-designing fine-tuning
- Use experiment agents (Stage 5) instead of manual hyperparameter search
- Use synthetic environments (Stage 6) instead of building simulators
- Validate with simulations (Stage 7) before human studies
- Run physical experiments (Stage 8) only for what must be physical
The 10% quality gap closes every year. The 100x cost advantage and 10,000x speed advantage compound.
You don’t need to build the pipeline. You need to know which stage you’re at — and use the tool that automated it.